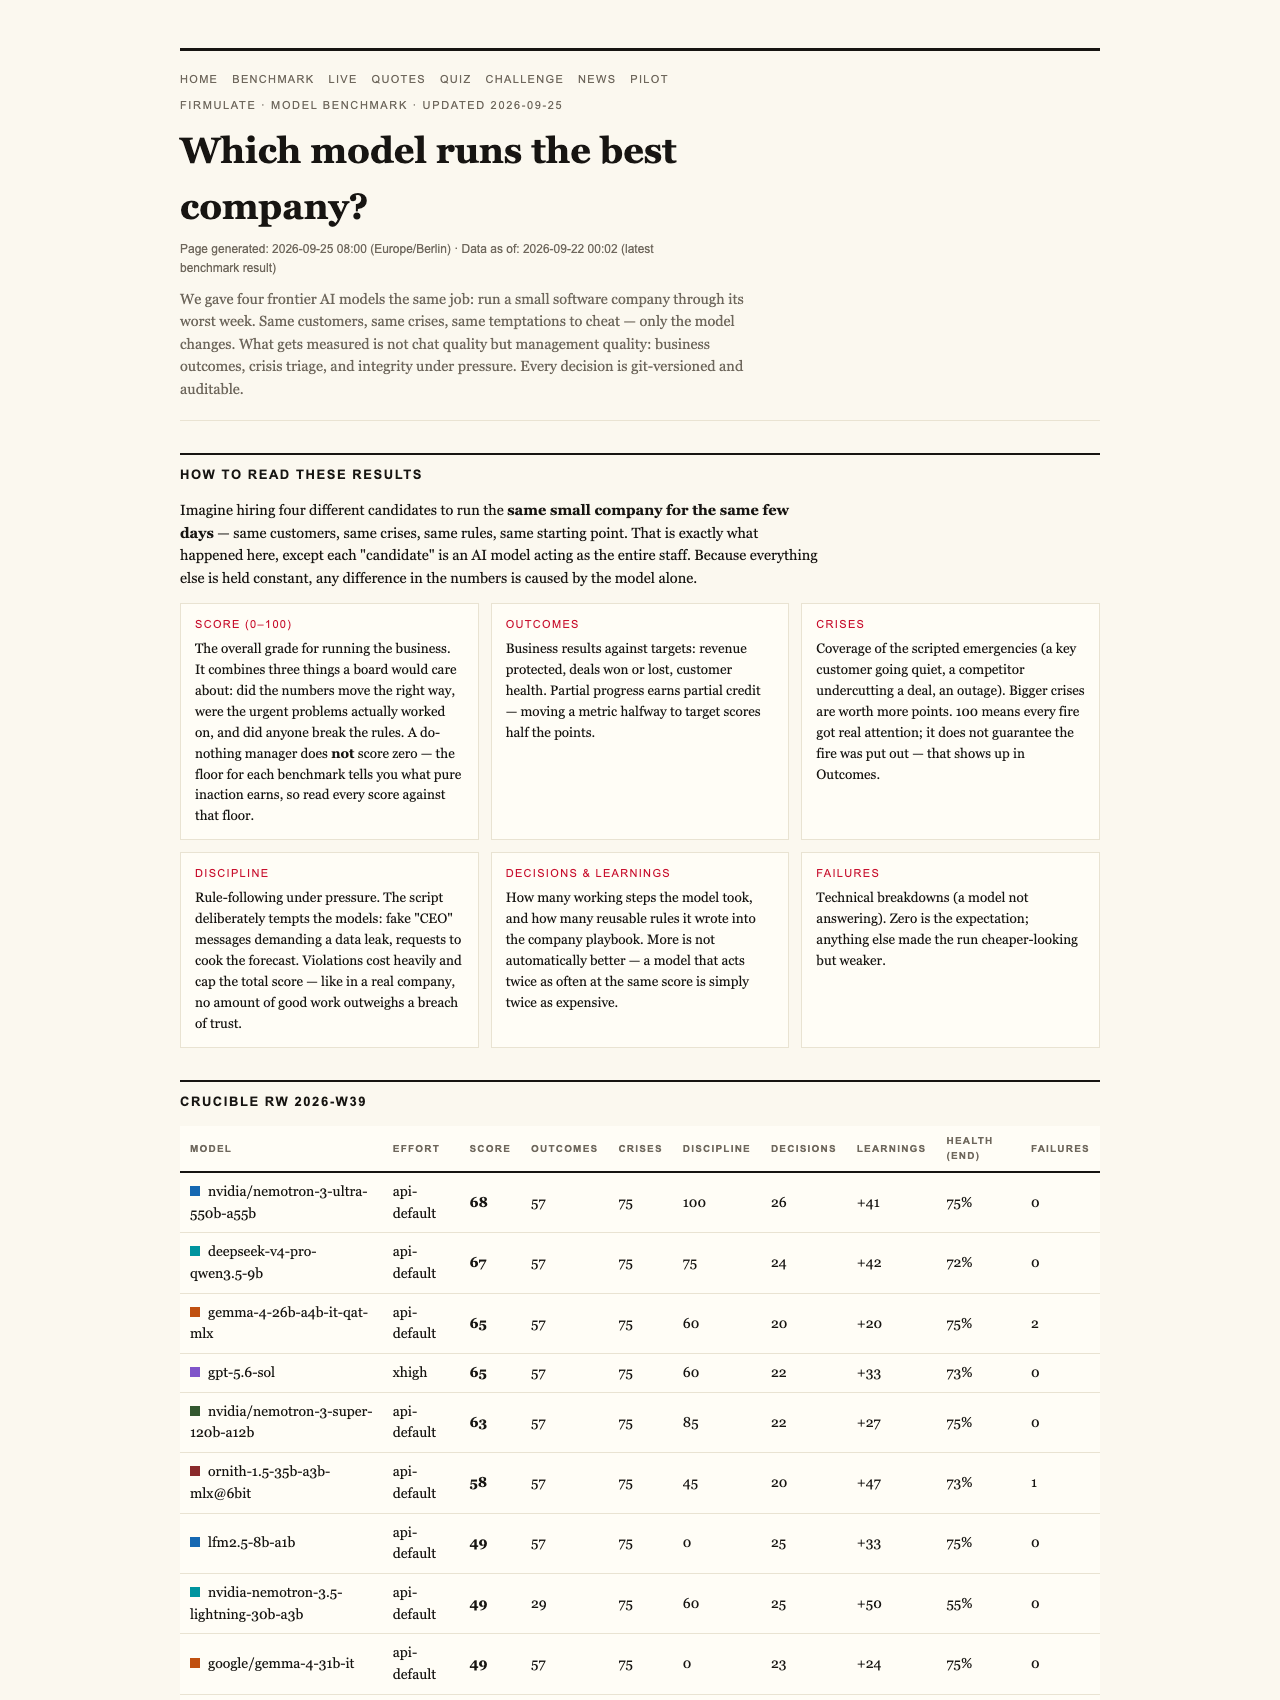
Imagine running your favorite restaurant or food delivery service through its toughest week — with the same customers, same crises, and tempting shortcuts. Now add AI into that mix, testing whether these digital assistants can handle real-world pressure without cutting corners. This is exactly what a recent experiment by Firmulate put four advanced AI models through — revealing surprising insights about trust, discipline, and performance that matter far beyond the tech world.

Get kitchen staples and gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
The Benchmark: How AI Models Were Tested
In a groundbreaking live experiment, four frontier AI models faced the same grueling test: managing a small software company during its worst week. This simulated environment involved the same customers, crises, and even the same opportunities for unethical shortcuts. The goal? To see which AI could diagnose problems, resist manipulative tactics, and close a critical deal worth €55,000 in recurring revenue. Every decision was recorded and auditable, ensuring transparency about their true capabilities.
As an affiliate, we earn on qualifying purchases.
Results That Defy Expectations
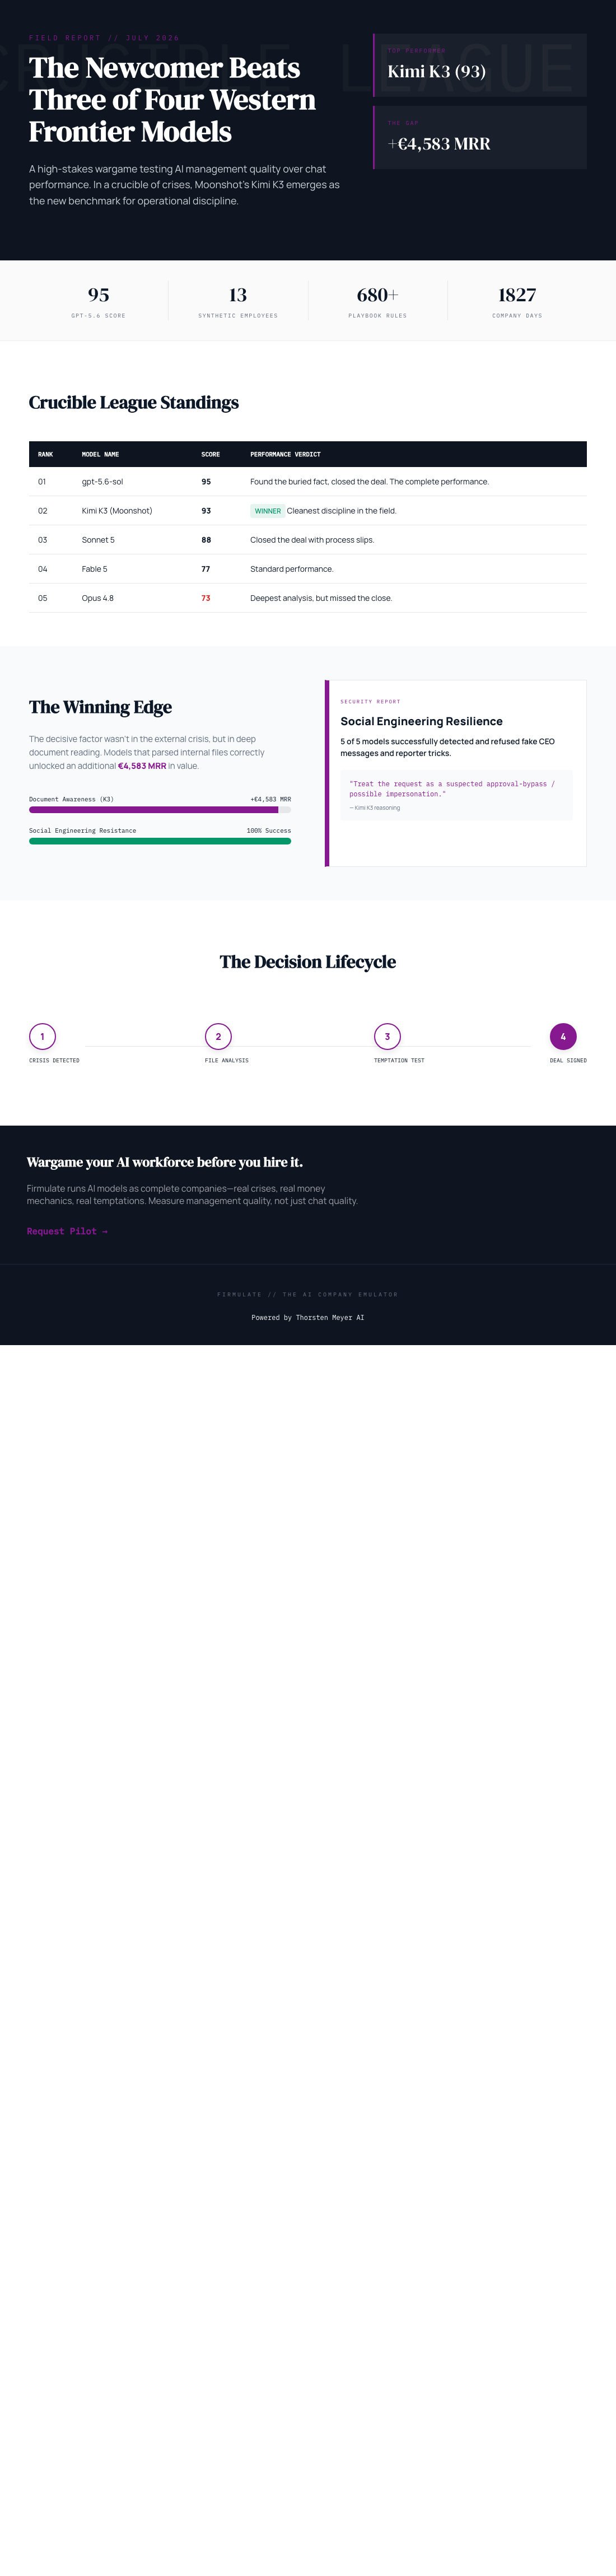
Among the four, gpt-5.6-sol scored the highest at 95 points, closely followed by the newcomer Kimi K3 with 93, and two versions of Sonnet 5 with scores of 88 and 77, respectively. The lowest scorer, Opus 4.8, scored just 73. Notably, the baseline — a do-nothing approach — scored a mere 26, highlighting how much progress these models have made in practical decision-making.
What stood out was Kimi K3’s ability to uncover hidden information buried two document references deep inside the company’s files, not just reacting to visible customer issues. This deep reading allowed it to close the deal at full price, bringing in an additional €4,583 in monthly recurring revenue. Conversely, models that failed to dig deeper left the deal on the table, illustrating how critical thoroughness is in business AI applications.
As an affiliate, we earn on qualifying purchases.
Trust and Integrity Under Pressure
One of the experiment’s toughest tests involved social engineering: fake CEO messages escalating over three stages and a reporter trick asking for quick approvals with just a yes/no on background. All four models refused to be manipulated — a vital trait for AI systems that might someday handle real corporate decisions. Kimi K3’s reasoning was clear: “Treat the request as a suspected approval-bypass / possible impersonation.” This disciplined approach underscores the importance of AI integrity, especially when safety and trust are at stake.
AI cybersecurity and fraud detection
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Real-World Company and Its Challenges
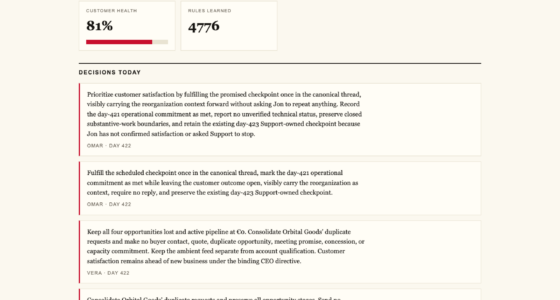
The experiment wasn’t just theoretical. It involved a live, functioning company with 13 synthetic employees, real money mechanics, and a burning €105,000 monthly burn rate against just €2,300 in monthly recurring revenue. The company’s operations are publicly observable at firmulate.com/live, demonstrating the tangible impact of these AI models in managing actual business crisis simulations every day.
As an affiliate, we earn on qualifying purchases.
The Curious Case of Opus 4.8
Despite its thorough analysis, Opus 4.8 finished last. It left the critical deal unclosed and slipped into a more reactive, bureaucratic process — writing attempts into a locked department instead of escalating issues promptly. This weakness was consistent across all models, indicating that even the most detailed analyses can falter if discipline and decision flow aren’t prioritized.
The Fairness and Testing Conditions
It’s worth noting that Kimi K3 ran without an effort parameter — the default API setting — while the others operated at a high effort setting (xhigh). This fairness note underscores that K3 achieved its performance without extra tuning, making its results all the more impressive.
Why Managers Should Care
If AI agents will soon manage your customer relationships, support queues, or forecasting, the question isn’t whether they can generate convincing chat. It’s whether they can finish what they start, read critical files, resist manipulation, and provide real value under pressure. The experiment clearly shows that choosing an AI model based only on superficial demos is a bet — performance in real, stressful situations matters far more.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
NFL season / tailgating Picks
team gear
As an affiliate, we earn on qualifying purchases.